INDUSTRY INSIGHTS · Lab automation & experimental design
JFAB’s AI lab update asks a harder question: what did the experiment teach you?
JBEI’s October 13, 2026 JFAB update connects AI and lab automation. BioMedAna examines experimental design, controls and the decisions behind a useful learning loop.
JBEI published its JFAB update:
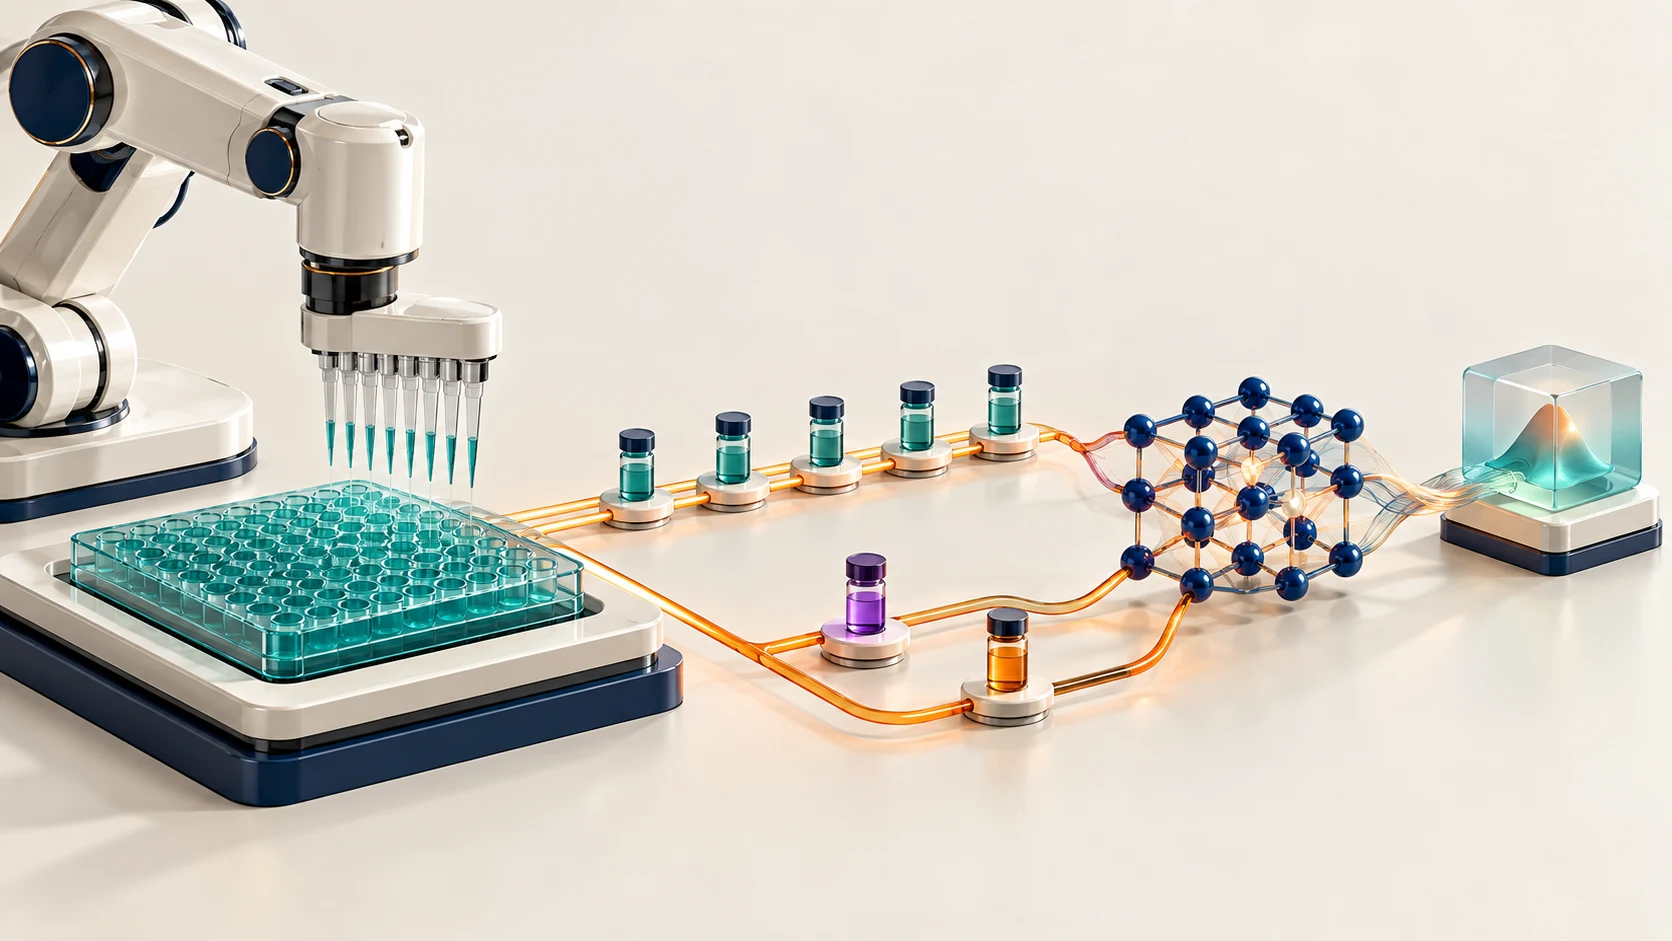
The news hook: an October 13 look at connected lab automation
On October 13, 2026, the Joint BioEnergy Institute published an update describing JFAB, its framework for AI-driven biomanufacturing. The update brings computational models, automated experiments and data management into one research workflow. It emphasizes standardized experimental datasets as an input to better models. This is a recent account of the platform’s approach, not evidence that JFAB first launched that day.
The setting matters. JBEI works in bioenergy and bioproducts; this update is not a report of a validated therapeutic-biologics manufacturing system. Our interest is the experimental operating model and what founders building scientific software can learn from it. The biologics scenarios below are our illustrations, not JFAB results.
Our take: a faster test is not automatically a better question
Automation makes it easier to execute a plan repeatedly. A founder still has to decide whether that plan creates information worth paying for. A plate full of successful repeats may improve confidence in a familiar condition while leaving the most important program uncertainty untouched. A smaller experiment that distinguishes two competing explanations can be more valuable to the next decision.
We would separate two objectives before building the workflow. One is improving a selected outcome under defined conditions. The other is learning whether a proposed explanation holds. These objectives can overlap, but they do not always choose the same next experiment. A system optimizing a score needs an explicit way for scientists to reserve work for controls, comparisons and unresolved hypotheses.
That is a practical product requirement: a proposed experiment should carry a reason for its selection. Is it exploiting a promising region, testing a boundary or checking whether an apparent improvement survives repetition? The reviewer should not have to infer that purpose from a ranked list of conditions.
The next experiment should have a reason that survives a disappointing result.THE BIOMEDANA LENS
A hypothetical protein-expression screen: when the batch becomes the explanation
Imagine a recombinant-protein team evaluating several feed conditions in a small-scale automated screen. A model recommends a set of promising conditions after an initial round. The follow-up runs occur on a different day with a different preparation of material. The best result improves. The team now has a decision to make: advance the recommended condition or investigate whether the comparison is trustworthy.
If every original condition belongs to one batch and every new condition belongs to another, a difference between batches can be difficult to separate from a condition effect. A tidy model report does not remove that ambiguity. We would discuss the comparison with the experimental scientist before treating the higher result as evidence that the recommendation worked.
One possible response is to include a reference condition across rounds, plan appropriate repeats and avoid assigning conditions in a way that makes a nuisance variable indistinguishable from the scientific variable. The precise design depends on the process, assay and available resources. Our point is not to prescribe a universal plate layout; it is to make the comparison question explicit before execution.
What should the automation plan preserve?
JFAB’s platform overview describes modular automation, AI/ML tools and data capture with provenance. Those capabilities support a useful architectural distinction: the experimental plan, what actually happened and the interpretation of the result should remain distinguishable. An execution exception must not silently become a scientific finding.
For the hypothetical screen, we would retain the planned condition, material identity, run assignment, execution deviations and assay context alongside the measurement. Then we would record whether the reviewer considered the result suitable for the intended comparison. That review state is different from whether the measurement looks favorable.
- State the decision and competing explanations before selecting the next conditions.
- Record why each condition was selected, including reference and repeat work.
- Preserve planned and actual execution separately, with exceptions attached to the affected results.
- Distinguish a raw observation, a processed metric and a scientific interpretation.
- Link a changed recommendation to the new evidence that justified it.
The founder tradeoff: spend the next slot on a favorite or on a doubt?
A small company has limited experimental capacity. Repeating a promising condition, testing a new region and investigating a suspicious result compete for the same time and materials. A useful AI workflow should help the team discuss that allocation rather than hide it inside an optimization routine.
We would ask scientists to identify the uncertainty with the greatest consequence for the next milestone. If a condition appears attractive but its advantage rests on a questionable comparison, a confirmation experiment may deserve priority. If the result is repeatable but its useful operating range is unclear, boundary testing may be more informative. Those are different reasons to spend the next slot.
This also changes how a founder evaluates a pilot. A higher best-observed score can be encouraging, but it is incomplete evidence of a better workflow. Ask whether the selected experiments reduced an uncertainty the team agreed mattered. Record the opportunity cost: which useful work was deferred, and why was that a reasonable choice?
What a failed run should change in the next cycle
An unfavorable measurement and an uninterpretable run should not automatically receive the same treatment. A condition can perform poorly in an otherwise valid experiment. A different run can produce a number that cannot support the planned comparison because an important execution detail is unresolved. Both records can be worth retaining, but the next action may differ.
Our design preference is a small set of review states with a short scientific rationale. A reviewer might accept a result for comparison, request a repeat or hold it pending clarification. The system should preserve the original observation and make a later change in interpretation visible. This lets the team revisit an assumption without rewriting its experimental history.
JBEI’s public Experiment Data Depot repository provides useful background on standardized biological experimental data and metadata. Its documentation describes storage, visualization and export. That is context for the importance of usable records; we do not infer from it which software components a particular JFAB workflow currently runs.
How we would judge a pilot before buying more automation
Select a recurring scientific decision and establish how the team currently reaches it. For the expression screen, the decision might be whether a proposed condition merits further characterization. Keep the pilot’s scope stable enough to compare the work, including preparation, experimental review and the handling of exceptions.
Then inspect the decision trail. Can a reviewer identify the hypothesis, the selected comparison and the result that changed the recommendation? How much time did the team spend resolving ambiguous records? Did an exception lead to an appropriate follow-up, or was it simply excluded? These questions reveal whether the workflow supports scientific reasoning under imperfect conditions.
We would treat claims about shorter timelines or lower costs as hypotheses to evaluate within that pilot. The October update does not establish a numeric benefit for a therapeutic-biologics program. A founder should make any eventual benefit claim at the level supported by the team’s own evidence.
What we would pass on to another builder
Before connecting another instrument, connect a proposed experiment to the decision it is meant to change. Give the scientific reviewer a clear choice among confirming, exploring and investigating. A reasoned allocation of scarce experimental capacity is a useful product feature even before the laboratory becomes highly automated.
For BioMedAna, the implication is to keep process context, analysis and reviewed next actions connected. An agent could help assemble the evidence for a planning discussion, but it should not quietly replace the scientist’s experimental acceptance criteria. Its contribution should be inspectable when the result is surprising.
JFAB’s recent update is a useful prompt to look beyond sample throughput. The durable question for a founder is whether the next cycle asks a better question than the last one. Build a workflow that can answer that with a retained plan, a fair comparison and an honest account of what remains unknown.
A practical experiment-allocation review
This illustrative framework helps a founder and scientific lead review a proposed automated round. It is BioMedAna’s analysis, not a description of JFAB’s internal selection rules.
| Purpose of the next experiment | Question to resolve | What would change the decision? |
|---|---|---|
| Confirm a promising condition | Does the apparent advantage persist in a suitable comparison? | A result that supports or weakens advancement of that condition. |
| Test a boundary | Where does the current interpretation stop being useful? | Evidence that narrows the operating range or requires another hypothesis. |
| Investigate an exception | Was the unfavorable outcome scientific, operational or unresolved? | A review that permits comparison, requests a repeat or changes the next plan. |
| Maintain a reference | Can this round be interpreted alongside earlier work? | Evidence that the comparison needs adjustment or further investigation. |
The questions behind the headline
Was JFAB launched on October 13, 2026?
The dated source is an October 13 update describing JFAB. We do not treat that publication date as the platform’s first launch date.
Does this demonstrate a validated biologics manufacturing system?
No. The sources discuss biomanufacturing research in JBEI’s bioenergy and bioproducts setting. The recombinant-protein example is BioMedAna’s hypothetical illustration; therapeutic applicability requires its own evaluation.
What should a founder measure first?
Choose a bounded scientific decision. Evaluate whether the workflow resolves the intended uncertainty, supports a fair comparison and preserves the evidence behind the next action. Sample count alone is insufficient.
Follow the evidence
- JBEI — JFAB: Accelerating Discovery in Biomanufacturing (October 13, 2026; current news hook) ↗
- JBEI — JFAB platform overview (technical background; accessed October 17, 2026) ↗
- Berkeley Lab Biosciences — October 13 JFAB update (same institution’s account, not independent validation) ↗
- JBEI — Experiment Data Depot repository (background on experimental records; accessed October 17, 2026) ↗
Original BioMedAna editorial analysis. The linked sources support the reported developments; examples, frameworks and product implications reflect our perspective.
Explore the underlying concepts
CONTINUE READING
More from the BioMedAna lens.
 AI-enabled biologics discovery
AstraZeneca is moving AI deeper into biologics. Who owns the handoff?
Read perspective ↗ Biologics development & CMC
Six months to IND readiness? Read the decisions behind the timeline.
Read perspective ↗ AI & experimental validation
Lonza and Onava put expression data inside the AI loop. That is the signal.
Read perspective ↗ AI adoption & protein engineering